China AI Index
Your go-to intelligence source for China's AI ecosystem
China AI Index
Your go-to intelligence source for China's AI ecosystem
Companies
Alibaba Alibaba
Ant Group Ant Group
Baidu Baidu
ByteDance ByteDance
Cambricon Cambricon
DeepSeek DeepSeek
Huawei Huawei
iFlyTek iFlyTek
MiniMax MiniMax
Moonshot AI Moonshot AI
Pony.ai Pony.ai
StepFun StepFun
Tencent Tencent
Compare
2022
2027
DeepSeek $7.4B
Moonshot AI $8.2B
Zhipu AI (Z.ai) $10.8B
CUMULATIVE RAISED · FEATURED
Products
ByteDance Doubao (豆包) 344.9M MAU
RedNote (Xiaohongshu) Xiaohongshu (小红书) 300M+ MAU
Alibaba Qwen (千问) 165.6M MAU
DeepSeek DeepSeek 127.1M MAU
Tencent Tencent Yuanbao (元宝) 57.4M MAU
NEWSFEED · LIVE SYNCED 02:57 AM
SEP 26, 2026 4 stories
Amid many thorny issues with China, Trump pushes to rename AI as superintelligence
South China Morning Post ↗
China’s AI-led transformation is taking shape. Why are some economists urging caution?
South China Morning Post ↗
Chinese AI models surge in global popularity — and Washington is worried
CNBC ↗
Xi-Trump summit: China and US find common ground on AI, tariffs and fentanyl
Funding
South China Morning Post ↗
SEP 25, 2026 8 stories
China's Economy Unbalanced, AI Deal Hard to Envision, Stephen Roach Says
Bloomberg ↗
China overtakes US as top workplace for elite AI researchers, study finds
Research
South China Morning Post ↗
China and the US are racing ahead on AI. Can they manage risks together?
South China Morning Post ↗
From Suzhou to AI: Singapore, China eye new playbook for economic ties
South China Morning Post ↗
FutureX Capital founder sees China AI opportunities, warns of robotics bubble
CNBC ↗
China's Xi urges U.S. to cooperate on AI
CNBC ↗
China fuels rush to turn AI video into an industry
Reuters ↗
Why US-China AI Talks Are About Risk Management
Bloomberg ↗
SEP 24, 2026 8 stories
US-China Rivalry Fuels Fierce AI Race: Live Q&A
Bloomberg ↗
B-2 Spirit, AI cooperation, no US-China conflict: key Xi-Trump takeaways so far
South China Morning Post ↗
Decision Tree Research CEO Gregory Allen on U.S.-China AI talks
Research
CNBC ↗
Trump, Xi Thrust Fierce US-China AI Rivalry Into Spotlight
Bloomberg ↗
Xi says China, US must keep AI under human control at Trump’s White House welcome
South China Morning Post ↗
Reps. Liccardo and Kiley on U.S.-China AI safety proposal: We need to give authority to private sector scientists
CNBC ↗
Trump Says No Moves Toward US, China AI Guardrails in Xi Summit
Bloomberg ↗
Trump and Xi Jinping Hold Talks in Washington on Trade, AI and More
Trump and Xi discussed AI during their Washington summit. Trump rebranded 'artificial intelligence' as 'Super Intelligence' and directed U.S. diplomats to use the term, the U.S. proposed a bilateral notification mechanism for national-security-related AI incidents, and China's commerce ministry confirmed the two countries held their first formal AI dialogue.
Policy
AP ↗
This Week
Items103
Companies10
Rounds9
Last sync02:57 AM
Most Active · This Week
Alibaba Alibaba 10
DeepSeek DeepSeek 9
CXMT CXMT 3
ByteDance ByteDance 3
Newsletter
Recode China AI
Weekly intelligence on China's AI ecosystem, from Tony Peng — straight to your inbox.
01
01.AI
PRIVATE BEIJING EST. 2023 ~200 STAFF
01.AI was founded in March 2023 by Kai-Fu Lee and built the open-source Yi model series before pivoting in early 2025 to commercial applications on top of DeepSeek's models, led by its global product PopAI. Most of its LLM training team moved to a joint lab with Alibaba Cloud in January 2025.
Valuation
$1B
Total Raised
$300M+
Yi-Lightning Text Closed
MoE flagship API model (Oct 2024). Ranked #6 on Chatbot Arena at launch — joint 3rd among LLM companies. 40% faster inference than prior Yi models. Final model before 01.AI halted pre-training in early 2025.
Context16K
Input $0.14/1M tokens
Output $0.14/1M tokens
View Docs ↗
Yi-Coder Code Open
Code model (Sep 2024); 1.5B and 9B variants; supports 52 programming languages; 128K context window.
Context128K
Input
Output
View Docs ↗
Yi-1.5 Text Open
Open-source series (May 2024); 6B–34B variants. Improved coding, math, reasoning, and instruction-following over original Yi.
Context—
Input
Output
View Docs ↗
Yi-VL-34B Multimodal Open
34B vision-language model (early 2024). Open-weight multimodal extension of Yi-34B.
Context—
Input
Output
View Docs ↗
Yi-34B Text Open
Founding open-source model (Nov 2023). Topped HuggingFace Open LLM Leaderboard and C-Eval at launch. 200K-token context variant (Yi-34B-200K) also available.
MMLU76.3/100
Context200K
Input
Output
View Docs ↗
Total Raised
$300M+
All rounds
Valuation
$1B
Post-money (approx.)
Last Round
2024
Most recent year
2023-11
Series A$300M
TencentXiaomiAlibaba CloudSinovation Ventures
2024-08
StrategicUndisclosed
Southeast Asian consortium
↗ Source: Crunchbase
AI-powered document workspace targeting global markets. Features chat-with-document, AI presentation generation, and visual understanding. Supports 200+ languages. Primary B2C revenue driver for 01.AI following the company's 2025 pivot away from LLM pre-training.
ChatDocumentsGlobalConsumer
01.AI
Watch 01.AI's Kai-Fu Lee on Pacing Frontier AI Development
01.AI
Bloomberg ↗
01.AI
Kai-Fu Lee Says China Will Win AI Reach Race
01.AI
Bloomberg ↗
01.AI
Former Google China Chief Kai-Fu Lee: China Will Win the AI Race for Reach
01.AI
Bloomberg ↗
01.AI
AI Pioneer Kai-Fu Lee’s Startup Targets Hong Kong IPO Next Year
Funding01.AI
Bloomberg ↗
01.AI
Kai-Fu Lee: The U.S. and China Are Winning Different AI Races
01.AI
WSJ ↗
01.AI
Watch 01.AI's Kai-Fu Lee on OpenClaw, China's AI Advances
Policy01.AI
Bloomberg ↗
01.AI
01.ai's Kai-Fu Lee: Why China will beat the US in consumer AI
Product01.AI
Financial Times ↗
01.AI
Watch 01.AI CEO on China's AI Development
01.AI
Bloomberg ↗
01.AI
AI agents to replace humans as basic units of a company, Kai-Fu Lee says
Model01.AI
South China Morning Post ↗
01.AI
01.AI Steps Back from Pretraining Frontier Models, Pivots to Enterprise and Sovereign AI
Kai-Fu Lee's 01.AI stopped pretraining its own frontier LLMs, choosing instead to build tailored solutions on top of open models such as DeepSeek's for enterprise and government clients in finance, gaming, and legal — and increasingly for "sovereign AI" deployments abroad. Lee said the company was preparing a new funding round and a 2027 IPO.
BusinessStrategySovereign AIEnterprise
DigiTimes ↗
DeepSeek
DeepSeek narrows China-US AI gap to three months, 01.AI founder Lee Kai-fu says
DeepSeek
Reuters ↗
01.AI
Is Pursuing AGI Too Ambitious for Chinese AI Startups?
Lee Kai-Fu's 01.AI announces it will stop training large language models, with part of its team joining an Alibaba joint lab — raising questions about whether independent AGI pursuit is viable in China.
AGI01.AIKai-Fu LeeAlibabaStartup StrategyChina AI
Recode China AI ↗
Alibaba
Chinese start-up 01.AI founder Lee Kai-fu denies asset sale to Alibaba Cloud
Alibaba
South China Morning Post ↗
01.AI
China AI Star Kai-Fu Lee Hits Startup Headwinds in U.S.
01.AI
The Information ↗
01.AI
01.AI's Yi-Coder challenges AI giants
01.AI
VentureBeat ↗
01.AI
AI Pioneer Kai-Fu Lee Aims to Bring China Its ChatGPT Moment
01.AI
Bloomberg ↗
01.AI
Chinese AI startup 01.AI looks to raise $200 mln -sources
Funding01.AI
Reuters ↗
01.AI
Tech unicorn 01.AI admits ‘oversight’ in naming AI model built on Meta’s Llama
Model01.AI
South China Morning Post ↗
01.AI
China start-up 01.AI hits US$1 billion value with top-ranked open-source model
Funding01.AI
South China Morning Post ↗
Kai-Fu Lee
Kai-Fu Lee
李开复
Founder & Chairman
Reference Table
All Models
Compare models across all 43 Chinese AI companies
Company ↕
Model ↕
Type ↕
AA Score ↕
Released ▼
Context ↕
Input ↕
Output ↕
AlibabaAlibaba
Compact embedding model init. from Qwen3.5-2B for constrained serving; Apache 2.0
Multimodal
—
2026-09-26
—
—
—
MeituanMeituan
1.6T/48B-active MoE; adds native image understanding to LongCat's coding/agent strengths; API preview only, no open weights yet, free via OpenCode
Multimodal
—
2026-09-25
1M
$0.30/1M tokens
$1.20/1M tokens
AlibabaAlibaba
Universal text/image/doc/video/audio embedding model (Alibaba ATH MaaS), init. from Qwen2.5-Omni-3B; Apache 2.0, weights open-sourcing soon
Multimodal
—
2026-09-23
—
—
—
Ant GroupAnt Group
6B text-rich design image model, native RGBA output, #1 open-weight model on Artificial Analysis UI/UX leaderboard; MIT license. Flagged by @AdinaYakup — not on tracked company list
Image Gen
2026-09-22
—
—
—
TencentTencent
Professional image-gen preview, 30% higher human-eval win rate vs Hy Image 3.0; on par with Seedream 5.0 Pro; API-only, $0.024/image
Image Gen
2026-09-22
—
—
—
XiaomiXiaomi
309B/15B MoE high-throughput omnimodal variant; MIT license
Multimodal
—
2026-09-22
1M
$0.14/1M tokens
$0.28/1M tokens
XiaomiXiaomi
102B/42B MoE omnimodal flagship; ties Grok 4.7 on Artificial Analysis Intelligence Index, beats Claude Opus 5 on key benchmarks; MIT license
Multimodal
46/100
2026-09-22
1M
$0.435/1M tokens
$0.87/1M tokens
AlibabaAlibaba
7B open-weights unified text-to-image + editing model; native transparent (RGBA) output; up to 10 reference images
Image Gen
2026-09-20
—
—
—
StepFunStepFun
600B MoE (27B active) flagship agent model for coding, finance, knowledge work; weights scheduled to open Oct 15
reasoning
2026-09-20
1M
$1.0/1M tokens
$2.7/1M tokens
Shengshu TechnologyShengshu Technology
Vidu S2 Closed
Real-time interactive digital-character model (resolution up to 720p from 540p in S1) plus real-time video-editing model; also previewing VR spatial video generation; credit-based API pricing (~$0.05/credit)
Video Gen
2026-09-15
—
—
—
DeepSeekDeepSeek
New Causal Encoder-Decoder architecture (552B MoE, 8B/16B active); claimed to beat flagship V4-Pro on performance/cost/speed; replaces V4-Pro in routing from Sept 14
Multimodal
39/100
2026-09-10
1M
$0.15/1M tokens
$0.6/1M tokens
Ant GroupAnt Group
124B total/5.5B active MoE native image+video multimodal model (understand→reason→act→verify); MIT licensed; flagged by Adina Yakup, org not in the original company list
Multimodal
25/100
2026-09-09
1M
—
—
ModelBestModelBest
2.5B-param on-device/edge model for agentic use (PCs, phones, robotics, IoT); trained with RL+OPD merging 16 expert models; beats larger Qwen3.5-4B on average score; Apache 2.0
Text
—
2026-09-09
128K
—
—
XiaomiXiaomi
Embodied world model with sequence variants for modeling continuous interactions; Apache 2.0; caught via Adina Yakup/HF tracking
Embodied
2026-09-08
—
—
—
XiaomiXiaomi
Smaller/faster sibling of MiMo-X-Pro-Preview in Xiaomi's new agentic MiMo-X series; invite-only preview
Text
—
2026-09-08
1M
—
—
XiaomiXiaomi
Next-gen agentic foundation model (~1T total/42B active MoE) for long-horizon task execution and tool use; invite-only preview via MiMo Desktop app; company claims performance near Claude Opus 4.6 in agent scenarios
Text
—
2026-09-08
1M
—
—
iFlyTekiFlyTek
293B-param (293B-A30B MoE) flagship base model trained entirely on domestic compute; upgraded coding/agent capability; API-only via Xingchen platform, not open-weighted
Text
—
2026-09-07
1M
—
—
Ant GroupAnt Group
Interactive image/video-to-video world model small enough to run on a single consumer GPU; caught via Adina Yakup/HF tracking, not the per-company search
Embodied
2026-09-05
—
—
—
AlibabaAlibaba
First open-weight VLM foundation model for autonomous driving; unifies 3D perception, driving VQA, and motion planning on a Qwen3.5-4B backbone; Apache 2.0
Embodied
2026-09-04
—
—
—
Ant GroupAnt Group
Finance-tuned build of Ling-3.0-flash for investment/agent workflows; 124B total/5.1B active, MIT license; already being quantized for llama.cpp
Text
23/100
2026-08-27
256K
—
—
TencentTencent
770B total/49B active MoE flagship with Gated DeepSeek Sparse Attention; beat GLM-5.3 and Kimi K3 in Tencent's internal blind eval; pitched as open-source coding/agent frontier
Text
—
2026-08-27
1M
$0.83/1M tokens
$2.5/1M tokens
AlibabaAlibaba
180B-parameter/ 6B parameters activated, A GDN + QSA hybrid architecture, muon optimizer adopted, early preview of the architecture used in Qwen4
Multimodal
—
2026-08-26
262K
$0.16/1M tokens
$0.47/1M tokens
Zhipu AI (Z.ai)Zhipu AI (Z.ai)
Zhipu's first natively multimodal GLM-5 model, 320B total/18B active, KDA+MLA hybrid attention, mHC adopted, tested anonymously as ox-alpha on OpenCode and OpenRouter
Multimodal
42/100
2026-08-26
1M
$0.075/1M tokens
$0.25/1M tokens
DeepSeekDeepSeek
Experimental multimodal (vision) variant of V4-Flash; positioned near Claude Opus 4.8 on agent benchmarks; API-only
Multimodal
—
2026-08-21
1M
$0.44/1M tokens
$1.32/1M tokens
SenseTimeSenseTime
Open-sourced 8B unified any-to-any model with native 4K image generation and improved editing
Multimodal
—
2026-08-21
32K
—
—
AlibabaAlibaba
27.78B dense model, Apache 2.0, text/image/video input, agent/coding gains over Qwen3.6-27B
Multimodal
34/100
2026-08-14
262K
$0.40/1M tokens
$3/1M tokens
Zhipu AI (Z.ai)Zhipu AI (Z.ai)
GLM-5.3 Open
Post-trained on the same 744B GLM-5.2 base; built for agentic coding & cyber defense; open weights/API pricing to follow after safety review
Text
34/100
2026-08-14
1M
$1.40/1M tokens
$4.40/1M tokens
MiniMaxMiniMax
Open-weight text-to-music model; generates full songs with sung vocals (up to 5 min) from lyrics + structured caption
Multimodal
—
2026-08-14
—
$0.15 per track
—
DeepSeekDeepSeek
GA release of flagship (was in preview since April); 1.6T total/49B active MoE, agentic gains
Text
36/100
2026-08-13
1M
$0.435/1M tokens
$0.87/1M tokens
AlibabaAlibaba
Faster/distilled 14B character-animation & replacement model from Tongyi Lab, Apache 2.0
Video Gen
2026-08-07
—
—
—
AlibabaAlibaba
Wan 3.0 Closed
Public beta all-in-one video gen/edit model; single continuous shot up to 30s, director-level camera moves, character/scene consistency, and doc/xls/ppt/pdf/md-to-video capability; no open weights (unlike Wan 2.2)
Video Gen
2026-08-06
—
—
—
Ant GroupAnt Group
Lightweight hybrid-reasoning MoE, 7.9B total/1.3B active, runs on Apple Silicon & NVIDIA DGX Spark
Text
15/100
2026-08-06
262K
—
—
ByteDanceByteDance
SeedRealtime Closed
Native audio-visual full-duplex LLM fusing audio/video/text streams for real-time watch, listen, speak interaction; replaces separate ASR/vision/TTS pipeline; live in Doubao app
Multimodal
—
2026-08-05
—
—
—
AlibabaAlibaba
Third-gen image model with ~4.5K-token ultra-long prompts, ~10px fine text rendering, native rendering in 12 languages, dense infographic/document layouts, reference-preserving edits; $0.04/image, API-only
Image Gen
2026-08-05
—
$0.003/image
$0.04/image
XiaomiXiaomi
VLA robot foundation model, Qwen3-VL backbone + Diffusion-Transformer (Mixture-of-Transformers); trained on 100,000+ hrs UMI data plus 7,200+ hrs real-robot data; demoed autonomous laundry folding, washer loading, suitcase packing
Embodied
2026-08-05
—
—
—
AlibabaAlibaba
2.4T MoE, ~95B active/token; text+image+video input; explicit reasoning (low/high/xhigh, xhigh default); flat pricing across full 1M ctx, max output 131K; open weights promised ~mid-Aug 2026 (HF/ModelScope)
Multimodal
45/100
2026-08-03
1M
$2.00/1M tokens
$6.0/1M tokens
RedNote (Xiaohongshu)RedNote (Xiaohongshu)
Lightest model in RedNote HiLab's dots3 series — 280B total / 16B active params (MoE), 512K context, natively understands text, images, and audio. An internal harness built on the model scored a certified perfect 42/42 (IMO gold) at IMO 2026.
Text
—
2026-08
512K
—
—
ByteDanceByteDance
Seedance 2.5 Closed
Native single-shot 30s video generation up to 4K, accepts up to 50 multimodal references; launched head-to-head vs MiniMax H3
Video Gen
2026-07-31
—
—
—
MiniMaxMiniMax
Omni-modal video generator (text/image/video/audio input), up to 15s native 2K video with native stereo audio; open weights planned within days
Video Gen
2026-07-31
—
—
—
DeepSeekDeepSeek
Public-beta API release; retrained V4-Flash beats DeepSeek's own larger V4-Pro-Preview on all 9 published agent/coding benchmarks
Text
34/100
2026-07-31
1M
$0.14/1M tokens
$0.28/1M tokens
SenseTimeSenseTime
Lightweight 8B-MoT open unified multimodal model (NEO-Unify architecture); adds native 4K image generation and stronger instruction-following edits vs prior U1
Image Gen
2026-07-31
—
—
—
HuaweiHuawei
505B-param MoE (18B active), open-sourced with weights, inference code & technical report; trained 100% on Huawei Ascend 910B NPUs
Text
—
2026-07-31
512K
—
—
AlibabaAlibaba
Qwen3.7-Flash Closed
Native vision-language Flash upgrade with stronger object recognition, spatial intelligence, and multimodal agent execution
Multimodal
—
2026-07-25
1M
$0.03/1M tokens
$0.13/1M tokens
Ant GroupAnt Group
124B-param MoE, only 5.1B active/token; hybrid-reasoning combines Ling speed + Ring reasoning; outperforms Ant's own 1T Ling-2.6 on 11/12 benchmarks; API-only (no open weights at launch), free on OpenRouter through 2026-08-03
Text
25/100
2026-07-23
256K
$0.021/1M tokens
$0.063/1M tokens
AlibabaAlibaba
ABot suite Closed
Amap's full-stack embodied AI upgrade: five models for navigation, manipulation, reasoning, memory, and motion control; claims SOTA on 17 benchmarks
Embodied
2026-07-22
—
—
—
TencentTencent
Vision-language-action model trained on 10,000+ hours of data, deployable across different robot platforms
Embodied
2026-07-19
—
—
—
TencentTencent
Perception model for robots; best-in-class on 19 of 38 benchmarks at 1/10th the compute of Tencent's prior flagship
Embodied
2026-07-19
—
—
—
TencentTencent
Reasoning engine for embodied cognition: joint language-visual reasoning, world-state prediction, subgoal planning; ships with open RxBrain-Bench
Embodied
2026-07-19
—
—
—
SenseTimeSenseTime
Unifies seeing, generating, acting via NEO-unify architecture; native 8K output; debuted at WAIC 2026
Multimodal
—
2026-07-19
—
—
—
Kunlun TechKunlun Tech
Mureka v9.5 Closed
AI music model with O3 reflective-reasoning + MuCo creation agent; pitched as least AI-sounding music generator, unveiled at WAIC
Multimodal
—
2026-07-19
—
—
—
Kunlun TechKunlun Tech
Interactive world-model upgrade shown at WAIC; 5B model, real-time 720p-class generation at 20FPS with 1-minute memory
Video Gen
2026-07-19
—
—
—
ModelBestModelBest
0.9B on-device VLA model for person-tracking, unveiled at WAIC 2026; SOTA on 3 tracking benchmarks, runs 5+ FPS on Unitree Go2 onboard compute
Embodied
2026-07-17
—
—
—
ModelBestModelBest
1.5B on-device VLA model for robot manipulation, unveiled at WAIC 2026; outperforms larger models like π0.5 and Qwen-VLA per ModelBest
Embodied
2026-07-17
—
—
—
WeRideWeRide
WITT Closed
Physical AI foundation model built on Atomic Physical Facts; claims 98% lower token cost and 200x data efficiency vs general models (self-reported, unverified)
Embodied
2026-07-17
—
—
—
UnisoundUnisound
U2-Med Closed
First tri-medical LLM spanning healthcare, insurance and pharma; built on U2 foundation model
Multimodal
—
2026-07-17
—
—
—
Moonshot AIMoonshot AI
Kimi K3 Open
Flagship model, 2.8T total parameters, strong coding and agent capabilities, open weights by July 27
Multimodal
44/100
2026-07-16
1M
$3.00/1M tokens
$15.00/1M tokens
Ant GroupAnt Group
Industry-first embodied-native causal video-action model; dual-stream mixture-of-transformers architecture, unifies frame prediction and policy execution from scratch
Embodied
2026-07-11
—
—
—
Ant GroupAnt Group
Open-source world model generating hour-long, no-decay 720p/60fps interactive experiences with built-in dynamic agents; up from minutes-level in v1.0
Embodied
2026-07-09
—
—
—
AlibabaAlibaba
DAMO Academy release; generates robot's predicted future as joint RGB + depth + optical-flow stream for manipulation planning, not just 2D video
Embodied
2026-07-08
—
—
—
Ant GroupAnt Group
6B open-source cross-embodiment model; trained on 60K hrs real-world data across 20 robot morphologies from 17 manufacturers
Embodied
2026-07-08
—
—
—
Ant GroupAnt Group
1.1B-param ViT-g/16 self-supervised vision model using masked boundary modelling, trained on ~161M curated images; 4 sizes released under Apache-2.0
Embodied
2026-07-07
—
—
—
Ant GroupAnt Group
Next-gen monocular depth model paired with LingBot-Vision; claims to roughly halve robotic depth-estimation error in challenging scenarios
Embodied
2026-07-07
—
—
—
TencentTencent
295B total / 21B active + 3.8B MTP layer, 192 routed experts (top-8) + 1 shared; official release upgrades Apr 2026 preview, deployed across WeChat, Yuanbao, WorkBuddy
Text
25/100
2026-07-07
256K
$0.18/1M tokens
$0.60/1M tokens
Shengshu TechnologyShengshu Technology
Vidu S1 Closed
Real-time interactive video model with voice-controlled avatars; 540p up to 42fps; runs on consumer-grade GPUs instead of server clusters
Video Gen
2026-07-03
—
—
—
Zhipu AI (Z.ai)Zhipu AI (Z.ai)
GLM-5.2 Open
753B params; Rolled out to all GLM Coding Plan tiers (Lite/Pro/Max/Team); standalone API + MIT open weights
Text
51/100
2026-06-01
1M
$1.40/1M tokens
$4.40/1M tokens
MiniMaxMiniMax
MiniMax-M3 Open
428B params (23B active); 1-million-token context window; novel attention mechanism called MSA; native multimodality
Multimodal
29/100
2026-06
1M
$0.30/1M tokens
$1.20/1M tokens
Moonshot AIMoonshot AI
1T total params / 32B active, 384 experts, ~30% lower reasoning-token usage vs K2.6
Code
26/100
2026-06
256K
$0.95/1M tokens
$4.00/1M tokens
StepFunStepFun
198B total / 11B active params; 1.8B ViT vision encoder; 3 reasoning levels (low/med/high); ~400 TPS; Apache 2.0; supports NVIDIA NIM on-prem deployment
Multimodal
—
2026-06
256K
$0.2/1M tokens
$1.15/1M tokens
MeituanMeituan
1.6T para + MoE; trained on 50,000 domestic Chinese chips; next-gen flagship
Text
19/100
2026-06
1M
$0.75/1M tokens
$2.95/1M tokens
XPengXPeng
VLA 2.0 Closed
Second-generation vision-language-action world model — deliberative reasoning, controllable generation, and long-horizon forecasting. Runs on 4 self-developed Turing AI chips (~3,000 TOPS effective) in the Robotaxi platform.
Embodied
2026-06
—
—
—
AlibabaAlibaba
Qwen3.7-Max Closed
Flagship closed-source reasoning model. Ranked #1 on Artificial Analysis Intelligence Index (29/100) out of 218 models at release. 1M token context window. Text-only (no multimodal). Architecture reportedly dual-72B. Extended thinking / chain-of-thought mode. Released May 19, 2026.
Text
29/100
2026-05
1M
$2.50/1M tokens
$7.50/1M tokens
BaiduBaidu
ERNIE 5.1 Closed
MoE successor to ERNIE 5.0. ~⅓ total params, ~½ active params, 6% of pre-training cost. AIME 2026: 99.6% with tool use (#2 globally). Arena Search: 1,223 (#4 global, #1 China). Released May 9, 2026.
Text
—
2026-05
128K
$0.59/1M tokens
$2.65/1M tokens
Baichuan AIBaichuan AI
Baichuan-M4 Closed
Medical AI flagship (May 2026). World #1 on HealthBench, HealthBench Hard & HealthBench Professional. Hallucination rate 3.3% — industry low via factuality-aware RL. Surpasses GPT-5.5, Opus 4.7, DeepSeek-V4-Pro. Powers 百小医 AI family doctor.
Text
—
2026-05
—
—
—
ModelBestModelBest
1.3B multimodal model (SigLip2 + Qwen3.5-0.8B). 260K token context. Runs on consumer phones (iOS/Android/HarmonyOS). Launched May 2026.
Multimodal
—
2026-05
260K
—
—
ModelBestModelBest
1B language model with 128K token context. SOTA on-device LLM at its size class. Apache 2.0.
Text
—
2026-05
128K
—
—
Zhipu AI (Z.ai)Zhipu AI (Z.ai)
GLM-5.1 Open
754B flagship — top scores on AIME 2026 (95.3) and GPQA-Diamond (86.2); strong agentic and coding ability
Text
—
2026-04
200K
$0.98/1M tokens
$3.08/1M tokens
MiniMaxMiniMax
229B MoE; self-evolving agent — 30% perf gain over 100+ rounds; agent teams, complex skills, 24/7 background agents
Agent
2026-04
1M tokens
$0.28/1M tokens
$1.20/1M tokens
Moonshot AIMoonshot AI
Kimi K2.6 Open
1T MoE (32B active), 256K ctx; native multimodal agentic — top SWE-Bench (80.2) and AIME 2026 (96.4)
Multimodal
—
2026-04
256K
$0.60/1M tokens
$2.50/1M tokens
DeepSeekDeepSeek
Flagship MoE: 1.6T total / 49B active params, 1M context, FP4+FP8 precision, built-in Think/Non-Think reasoning modes. Codeforces rating 3206.
Text
—
2026-04
1M
$0.435/1M tokens
$0.87/1M tokens
DeepSeekDeepSeek
Efficient MoE: 284B total / 13B active params, 1M context. Same architecture as V4-Pro at far lower compute cost. Codeforces 2816.
Text
—
2026-04
1M
$0.14/1M tokens
$0.28/1M tokens
BaiduBaidu
8B single-stream Diffusion Transformer (DiT). Best text rendering in open source (LongTextBench: 0.9733). Up to 4K output. Apache 2.0. Released Apr 15, 2026.
Image Gen
2026-04
—
$0.03/image
—
Ant GroupAnt Group
1T total params, ~63B active per token; adaptive reasoning via high / xhigh modes; up to 66K output tokens; open weights (MIT); released May 8 2026; free tier available on OpenRouter
Text
—
2026-04
262K
$0.075/1M tokens
$0.625/1M tokens
Ant GroupAnt Group
1T total params, ~63B active per token; fast thinking approach cuts token cost to ~1/4 of comparable models; open weights (MIT); released Apr 23 2026; free tier available on OpenRouter via Novita AI
Text
17/100
2026-04
262K
$0.075/1M tokens
$0.625/1M tokens
Ant GroupAnt Group
Efficient sparse MoE: 104B total / 7.4B active, hybrid linear attention. 340 tokens/s on 4× H20. Strong agent and tool-use performance.
Text
—
2026-04
262K
$0.10/1M tokens
$0.30/1M tokens
TencentTencent
Hy3-preview Closed
295B MoE (21B active); reasoning, coding, and agentic workloads. Via Tencent Cloud TokenHub. Released Apr 23, 2026.
Text
—
2026-04
256K
¥1.2/1M tokens
¥4.0/1M tokens
XiaomiXiaomi
1.02T MoE, 42B active; KV-cache reduced ~7×; latest generation
Text
26/100
2026-04
1M
$0.0036/1M tokens
$0.087/1M tokens
AGIBotAGIBot
AGIBot's new-generation embodied foundation model, powering autonomous manipulation and locomotion across its AGIBOT A2 and X2 robot lines.
Embodied
2026-04
—
—
—
XiaomiXiaomi
MiMo-V2-Pro Closed
1T+ MoE, 42B active; hybrid attention; 1M token context
Text
—
2026-03
1M
$0.0036/1M tokens
$0.087/1M tokens
Unitree RoboticsUnitree Robotics
Vision-Language-Action model enabling the G1 humanoid to autonomously perform household tasks from natural language commands. Runs onboard the robot. Open-sourced March 2026 — Unitree's first AI model release.
Embodied
2026-03
N/A
—
—
Kunlun TechKunlun Tech
SkyReels V4 Closed
Audio-visual creation model (Mar 2026). Dual-stream architecture; #1 globally on Text-to-Video (With Audio) and Image-to-Video (With Audio) tracks at release. Generates clips up to 3 minutes.
Video Gen
2026-03
—
—
—
Kunlun TechKunlun Tech
Mureka V9 Closed
Music generation model (Mar 2026). Paragraph-level text control; enhanced mixing quality, vocal expression, and style richness.
Audio
2026-03
—
—
—
Kunlun TechKunlun Tech
Physics-simulation interactive world model (Mar 2026). 5B params; 720P @ 40FPS; covers 1,000+ scenarios with Unreal Engine data. Industrial-grade real-time interactivity.
Text
—
2026-03
—
—
—
ByteDanceByteDance
Seed2.0 Pro Closed
ByteDance's flagship multimodal model. Understands text, image, and video. Ranks #3 globally on LMSYS Vision Arena and #6 on overall text arena. AIME 2025: 98.3, SWE-bench: 76.5%.
Multimodal
—
2026-02
272K
$0.47/1M tokens
$2.37/1M tokens
ByteDanceByteDance
Unified multimodal image generation with chain-of-thought visual reasoning, real-time web search, and native editing. Supports up to 14 reference images. Up to 4K output at 2048×2048.
Image Gen
2026-02
—
$0.026/image
—
ByteDanceByteDance
Seedance 2.0 Closed
Unified audio-video joint generation model. Accepts text, image, video, and audio inputs; outputs native 2K video (up to 15s) with synchronized audio. 30% faster than Seedance 1.5 Pro.
Video Gen
2026-02
—
—
—
AlibabaAlibaba
Qwen3.5 Open
Unified vision-language MoE family. Flagship: 35B-A3B (35B total / 3B active) and 397B-A17B. Thinking mode on by default. Supports image, video, text input. 201 languages. Apache 2.0.
Multimodal
—
2026-02
262K (1M w/ YaRN)
—
—
AlibabaAlibaba
80B total / 3B active MoE coding agent. Excels at long-horizon agentic tasks, tool use, and IDE integration (Claude Code, Cline, Qwen Code). No thinking mode.
Code
—
2026-02
256K
—
—
Zhipu AI (Z.ai)Zhipu AI (Z.ai)
GLM-5 Open
754B MoE (40B active); 28.5T token pre-training; top-tier SWE-bench score of 77.8
Text
—
2026-02
200K
$1.40/1M tokens
$4.40/1M tokens
MiniMaxMiniMax
229B; SOTA SWE-Bench (80.2); 80% of MiniMax's own code generated by this model; M2.5-Lightning at 100 tok/s
Agent
2026-02
1M tokens
$0.30–$1.00/hr
$0.30–$1.00/hr
BaiduBaidu
ERNIE 5.0 Closed
2.4 trillion parameter unified multimodal (text + image + video + audio) in a single autoregressive framework. LMArena Text: 1,460 (#1 China, #8 global); Vision: 1,226 (#1 China, #8 global). Released Feb 6, 2026.
Multimodal
—
2026-02
128K
—
—
Ant GroupAnt Group
Open-source VLA foundation model trained on ~20,000 hours of real-world dual-arm robot data across 9 embodiments
Embodied
2026-02
—
—
—
Ant GroupAnt Group
World's first open-source 1T-parameter thinking model. Gold medal level at IMO 2025 (35/42 pts) and CMO 2025 (105/126). 3× throughput for sequences >32K.
Text
—
2026-02
256K
—
—
Ant GroupAnt Group
Any-to-any omni model: accepts image, text, video, and audio; outputs image, text, and audio. 100B total / 6B active MoE. Supports zero-shot voice cloning and image generation/editing.
Multimodal
—
2026-02
—
—
—
Ant GroupAnt Group
Novel diffusion-based language model — not autoregressive. 103B params. Generates text by iterative token editing rather than left-to-right decoding. 102K monthly downloads.
Multimodal
—
2026-02
—
—
—
Baichuan AIBaichuan AI
235B medical model (Feb 2026) built on Qwen3 architecture. Former world #1 on HealthBench. Hallucination rate 3.5%. Outperforms human doctors in diagnostic accuracy. 48GB VRAM with W4 quantization.
Text
—
2026-02
—
—
—
JD.comJD.com
Open-sourced lightweight model — 4.8B total / 3B active params, pretrained on 20T text tokens. Released on HuggingFace as part of JD's open-source push.
Text
—
2026-02
—
—
—
Moonshot AIMoonshot AI
Kimi K2.5 Open
1T MoE (32B active); trained on 15T vision+text tokens; thinking & instant modes; agent swarm support
Multimodal
—
2026-01
256K
$0.40/1M tokens
$1.90/1M tokens
DeepSeekDeepSeek
3B visual OCR model with document-to-markdown conversion, layout-aware grounding, and dynamic resolution. 1.66M monthly downloads.
Multimodal
—
2026-01
—
—
—
TencentTencent
80B MoE (13B active); text-to-image and image-to-image with reasoning. Open weight on HuggingFace. Released Jan 26, 2026.
Image Gen
2026-01
—
—
—
MeituanMeituan
68.5B MoE, 2.9–4.5B active; fast and efficient
Text
—
2026-01
256K
—
—
AIsphereAIsphere
PixVerse R1 Closed
Real-time world model; 1080p, <15s latency, physics-aware, infinite temporal continuity
Video Gen
2026-01
N/A
—
—
SenseTimeSenseTime
Real-time multimodal streaming model. Powers SenseChat's live audio/video interaction. Successor to V6 Pro.
Multimodal
—
2026-01
—
—
—
LimX DynamicsLimX Dynamics
LimX's Vision-Language-Action embodied-AI engine powering autonomous manipulation and locomotion on its humanoid and legged robots.
Embodied
2026
—
—
—
DeepSeekDeepSeek
685B MoE with DeepSeek Sparse Attention (DSA). V3.2-Speciale variant won gold at 2025 IMO and IOI. 4.16M monthly downloads on HuggingFace.
Text
—
2025-12
128K
$0.252/1M tokens
$0.378/1M tokens
KuaishouKuaishou
Kling I2V 2.0 Closed
Image-to-video with industry-leading subject preservation
Multimodal
—
2025-12
N/A
$0.16/video (5s)
—
XiaomiXiaomi
309B MoE, 15B active; trained on 27T tokens; open-source release
Text
22/100
2025-12
N/A
$0.01/1M tokens
$0.30/1M tokens
AIsphereAIsphere
PixVerse V5.5 Closed
Text/image-to-video; HD output, multiple aspect ratios, character consistency
Video Gen
2025-12
N/A
—
—
TencentTencent
Hunyuan3D 3.0 Closed
3D asset generation from text, image, or sketch input
3D Gen
2025-11
—
—
—
iFlyTekiFlyTek
Spark X1.5 Closed
MoE reasoning model (29.3B total / 3B active parameters). Supports 130+ languages. Runs on a single Huawei Ascend server. Launched Nov 2025.
Text
—
2025-11
—
—
—
MiniMaxMiniMax
MiniMax-M2 Open
230B MoE (10B active); interleaved thinking; open-source under Modified MIT; free API available
Agent
2025-10
1M tokens
—
—
Infinigence AIInfinigence AI
MoE edge model: 3×7B experts, 3B active parameters. Open-weight, Apache 2.0.
Text
—
2025-09
—
—
—
AlibabaAlibaba
Qwen-Image Open
Image generation and editing foundation model. Exceptional Chinese + English text rendering. Supports style transfer, object insertion/removal, layered editing, and depth/edge estimation. Released Aug 2025.
Image Gen
2025-08
—
—
—
ModelBestModelBest
8B multimodal model (Qwen3-8B + SigLIP2). Apache 2.0.
Multimodal
—
2025-08
—
—
—
Moonshot AIMoonshot AI
Kimi k2 Open
Agentic model with tool use, web browsing, and code execution
Text
—
2025-07
128K
$0.57/1M tokens
$2.30/1M tokens
MiniMaxMiniMax
MiniMax-M1 Open
First open-weight large-scale hybrid-attention reasoning model; test-time compute scaling
Text
—
2025-06
1M tokens
$0.80/1M tokens
$2.20/1M tokens
MiniMaxMiniMax
Hailuo-02 Open
Physics-aware video generation; top-3 globally on VBench
Video Gen
2025-06
N/A
$0.06/video (5s)
—
Shengshu TechnologyShengshu Technology
Vidu Q3 Closed
World's first storytelling-focused video model. Up to 16 sec, 1080p 24fps, native audio sync. Multilingual. Pro and Turbo variants. MCP integration.
Video Gen
2025-06
—
~$0.07/sec
—
HuaweiHuawei
718B-parameter MoE model (256 experts), trained on the full-stack hardware and software of Huawei Cloud's AI Cloud Service (CloudMatrix 384 supernodes). Part of the Pangu Models 5.5 family, which per Huawei Cloud's own release delivers upgrades across five capabilities: natural language processing, computer vision, multimodal, prediction, and scientific computing.
Text
—
2025-06
—
—
—
RedNote (Xiaohongshu)RedNote (Xiaohongshu)
dots.llm1 Open
RedNote's first open-source LLM — 142B total / 14B active params (MoE), pretrained on 11.2T high-quality tokens with no synthetic data. Performance comparable to Alibaba's Qwen2.5-72B.
Text
—
2025-06
32K
—
—
DeepSeekDeepSeek
Latest R1 update: 685B, adds system prompt support, deeper reasoning (23K avg tokens on AIME vs 12K prior). Distilled 8B version achieves 86% on AIME 2024.
Text
—
2025-05
128K
$0.50/1M tokens
$2.15/1M tokens
KuaishouKuaishou
Kling 2.0 Closed
4K-capable video generation; advanced camera controls and scene coherence
Video Gen
2025-04
N/A
$0.16/video (5s)
—
KuaishouKuaishou
Kolors 2.0 Open
Upgraded photorealistic image model; open-source available
Image Gen
2025-04
N/A
$0.004/image
—
SenseTimeSenseTime
620B MoE hybrid. Real-time audio/video streaming. Ranked #1 in China in multimodal reasoning at launch. Lowest reasoning cost in industry at launch (Apr 2025).
Multimodal
—
2025-04
256K
¥2.8/1M tokens
¥8.4/1M tokens
Kunlun TechKunlun Tech
Open-source math and coding reasoning model (Apr 2025). 32B params; rivals DeepSeek-R1 on competitive programming benchmarks. 7B variant also available.
Text
—
2025-04
—
—
—
Qihoo 360Qihoo 360
Latest open-weight 360Zhinao generation (Base / Instruct / O1.5 long chain-of-thought reasoning variant). Free for commercial use.
Text
—
2025-04
32K
—
—
BaiduBaidu
ERNIE X1 Closed
Baidu's first dedicated reasoning model with extended chain-of-thought
Text
—
2025-03
128K
$0.28/1M tokens
$1.10/1M tokens
BaiduBaidu
ERNIE 4.5 Closed
Improved multimodal and reasoning; best ERNIE for Chinese enterprise tasks. The flagship ERNIE 4.5 model is closed-source, though several variants in the ERNIE 4.5 family are openly available on HuggingFace.
Multimodal
—
2025-03
128K
$0.55/1M tokens
$2.20/1M tokens
StepFunStepFun
Step-3 Closed
StepFun's 2025 flagship; 1M token context and native reasoning mode
Text
—
2025-01
1M
$0.57/1M tokens
$1.42/1M tokens
Baichuan AIBaichuan AI
32B medical reasoning model (2025) built on Qwen2.5-32B with innovative Large Verifier System for real-world clinical reasoning.
Text
—
2025-01
—
—
—
ModelBestModelBest
8B any-to-any model (text + vision + speech). Surpasses GPT-4o and Gemini 1.5 Pro on single-image understanding benchmarks. Launched Jan 2025.
Multimodal
—
2025-01
—
—
—
KuaishouKuaishou
Kling 1.6 Pro Closed
Previous flagship; supports 1080p, 5-10s clips, camera controls
Video Gen
2024-12
N/A
$0.14/video (5s)
—
Infinigence AIInfinigence AI
3B omni model processing text, vision, and audio. Outperforms LLaVA-NeXT-Yi-34B on vision benchmarks. Optimised for on-device and edge deployment.
Multimodal
—
2024-12
—
—
—
Kunlun TechKunlun Tech
Skywork-o1 Open
Reasoning model (Nov 2024) — among China's first o1-style models with chain-of-thought Chinese logical reasoning. Open-source 8B variant (Llama 3.1 base) plus proprietary advanced version.
Text
—
2024-11
—
—
—
Qihoo 360Qihoo 360
Second-generation 360Zhinao with Base and Chat variants at 4K / 32K / 360K context lengths.
Text
—
2024-11
360K
—
—
Baichuan AIBaichuan AI
Enterprise flagship general LLM (late 2024). 10%+ usability gain vs prior generation; priced at ~80% of GPT-4o. Supports multimodal input.
Text
—
2024-10
192K
—
—
Baichuan AIBaichuan AI
Baichuan4-Air Closed
MoE variant (PRI architecture) of Baichuan4. High performance at low cost for API deployments.
Text
—
2024-10
192K
—
—
01.AI01.AI
Yi-Lightning Closed
MoE flagship API model (Oct 2024). Ranked #6 on Chatbot Arena at launch — joint 3rd among LLM companies. 40% faster inference than prior Yi models. Final model before 01.AI halted pre-training in early 2025.
Text
—
2024-10
16K
$0.14/1M tokens
$0.14/1M tokens
01.AI01.AI
Yi-Coder Open
Code model (Sep 2024); 1.5B and 9B variants; supports 52 programming languages; 128K context window.
Code
—
2024-09
128K
—
—
iFlyTekiFlyTek
Spark 4.0 Closed
Flagship LLM (Aug 2024). Claims comparable performance to GPT-4 Turbo on Chinese language benchmarks.
Text
—
2024-08
—
—
—
StepFunStepFun
Step-2 Closed
Very long context window; strong document understanding
Text
—
2024-07
256K
¥0.038/1K tokens
¥0.12/1K tokens
StepFunStepFun
Step-1X-Image Closed
High-resolution image generation model
Image Gen
2024-07
N/A
¥0.04/image
—
01.AI01.AI
Yi-1.5 Open
Open-source series (May 2024); 6B–34B variants. Improved coding, math, reasoning, and instruction-following over original Yi.
Text
—
2024-05
—
—
—
Qihoo 360Qihoo 360
Retrieval + 1.8B reranking models that ranked #1 in the Retrieval and Reranking tasks of the C-MTEB leaderboard.
Embedding
2024-05
—
—
—
01.AI01.AI
Yi-VL-34B Open
34B vision-language model (early 2024). Open-weight multimodal extension of Yi-34B.
Multimodal
—
2024-01
—
—
—
01.AI01.AI
Yi-34B Open
Founding open-source model (Nov 2023). Topped HuggingFace Open LLM Leaderboard and C-Eval at launch. 200K-token context variant (Yi-34B-200K) also available.
Text
—
2023-11
200K
—
—
Kunlun TechKunlun Tech
Founding open-source bilingual LLM (Oct 2023). 13B params; pretrained on 3.2T tokens. Led same-scale models on CEVAL, CMMLU, and MMLU at launch.
Text
—
2023-10
—
—
—
Baichuan AIBaichuan AI
Baichuan2 Open
Open-source bilingual LLM series (Sep 2023); 7B and 13B variants; trained on 2.6T tokens. Available on Hugging Face under permissive license.
Text
—
2023-09
4K
—
—
JD.comJD.com
JD's 100B-parameter industry-focused LLM, blending 70% general data with 30% native supply-chain intelligence data for retail, logistics, finance, healthcare, and city-services applications.
Text
—
2023-07
32K
—
—
BaiduBaidu
ERNIE-Speed Closed
Free tier for prototyping and light production
Text
—
—
128K
—
—
MeituanMeituan
Image generation model, ~6B params; data-quality focused; released Dec 2025
Image Gen
—
N/A
—
—
MeituanMeituan
Text-to-video generation model; released Oct 2025
Video Gen
—
N/A
—
—
MeituanMeituan
Text + vision + audio multimodal
Multimodal
—
—
256K
—
—
MeituanMeituan
Chain-of-thought reasoning variant of LongCat-Flash
Text
—
—
256K
—
—
MeituanMeituan
560B MoE, 27B active; open-source; 500K free tokens/day
Text
—
—
128K
—
—
WeRideWeRide
Generative Engineered Neural Environment for Simulated Intelligence in Self-driving. WeRide's proprietary general-purpose simulation platform combining physical AI with generative AI. Rapidly builds photorealistic simulated cities in minutes, generates diverse edge-case scenarios from billions of km of real-world data, and models realistic pedestrian and driver behavior — all at centimeter-level fidelity. Supports L2++ through L4 AV development and validation via four modules: AI Scenarios, AI Agents, AI Metrics, and AI Diagnosis.
Embodied
—
—
—
—
Pony.aiPony.ai
PonyWorld 2.0 Closed
Second-generation world model underpinning the Virtual Driver L4 autonomous driving platform. Introduces an Intention layer — a structured representation of decision-making that enables the system to evaluate its own driving decisions, identify accuracy gaps across scenarios, and direct targeted data collection rather than broad undirected improvement. Direct sensor-to-action architecture with no language models in the inference pipeline; runs on 1016 TOPS across three NVIDIA DRIVE Orin-X SoCs with redundant failover.
Embodied
—
—
—
—
UnisoundUnisound
60B+ parameter general large model (v5.0); underpins all Unisound vertical products. Medical, enterprise, and consumer deployments.
Text
—
—
—
—
—
UnisoundUnisound
U2-ASR 2.5 Closed
First LLM-based semantic ASR model for Chinese. Covers 100+ dialects across 7 dialect systems. >90% accuracy. Available via Token Hub API.
Audio
—
—
—
—
UnisoundUnisound
Text-to-speech and voice cloning with full-duplex millisecond response. Available via Token Hub API.
Audio
—
—
—
—
UnisoundUnisound
U1-OCR Closed
Industrial-grade document intelligence model for OCR and document understanding. Launched February 2026.
Multimodal
—
—
—
—
—
Disclosed, 2026 YTD
Funding & Markets
Private funding rounds and public market data for China's leading AI companies
43
Companies tracked
23 public · 20 private
~$34.9B
AI startup funding
12 AI-native cos
Compare companies →
Valuation, total funding & AI ARR, side-by-side
Most Active Investors
1 Tencent
16
2 HongShan Capital
12
3 Alibaba
12
4 IDG Capital
9
5 Shunwei Capital
7
Derived live from 170 rounds
ByteDance
ByteDance
PRIVATE
Valuation$600B
Total Raised~$42.21B+
AI ARR$4B
Alibaba
Alibaba
BABA / 9988.HK
Market Cap—
Cloud Revenue (FY25)¥158B
AI ARR¥10B
Zhipu AI (Z.ai)
Zhipu AI (Z.ai)
2513.HK
Market Cap—
Total Raised$10.79B
AI ARR$1.6B
MiniMax
MiniMax
0100.HK
Market Cap—
Total Raised$2.17B
AI ARR$800M
Moonshot AI
Moonshot AI
PRIVATE
Valuation$35B
Total Raised~$8.2B+
AI ARR$1B
DeepSeek
DeepSeek
PRIVATE
Valuation$50B
Total Raised$7.35B
AI ARR$1B
StepFun
StepFun
PRIVATE
Valuation$10B
Total Raised$3.23B+
Last Round2026
Baidu
Baidu
BIDU / 9888.HK
Market Cap—
ExchangeNASDAQ: BIDU · HKEX: 9888
Founded2000
Ant Group
Ant Group
PRIVATE
Valuation$79B
Total Raised$20.53B+
Last Round2020
Tencent
Tencent
0700.HK
Market Cap—
Revenue (FY25)¥751.8B
Founded1998
Kuaishou
Kuaishou
1024.HK
Market Cap—
ExchangeHKEX: 1024
Kling ARR$500M
Xiaomi
Xiaomi
1810.HK
Market Cap—
Revenue (FY25)¥457.3B
Founded2010
Meituan
Meituan
3690.HK
Market Cap—
Revenue (FY25)¥364.9B
Founded2010
AIsphere
AIsphere
PRIVATE
Valuation$2B
Total Raised~$669M+
Last Round2026
Unitree Robotics
Unitree Robotics
688836.SS
Market Cap—
FY2025 Revenue¥1.71B
Founded2016
SenseTime
SenseTime
0020.HK
Market Cap—
Revenue (FY25)¥5.01B
Founded2014
Baichuan AI
Baichuan AI
PRIVATE
Valuation$2.7B
Total Raised$1.04B
Last Round2024
01.AI
01.AI
PRIVATE
Valuation$1B
Total Raised$300M+
Last Round2024
Kunlun Tech
Kunlun Tech
300418.SZ
Market Cap—
Revenue (FY25)¥8.2B
Founded2008
Evoken
Evoken
PRIVATE
Valuation$2B
Total Raised$430M+
Last Round2026
iFlyTek
iFlyTek
002230.SZ
Market Cap~¥190B
FY2025 Revenue¥27.1B
Founded1999
Infinigence AI
Infinigence AI
PRIVATE
ValuationUndisclosed
Total Raised~$251M+
Last Round2026
Enflame Technology
Enflame Technology
688801.SS
Market Cap—
FY2025 Revenue¥990.2M
Founded2018
SiliconFlow
SiliconFlow
PRIVATE
Valuation¥7.7B
Total Raised$419M
Revenue¥55.3M
Cambricon
Cambricon
688256.SS
Market Cap—
FY2025 Revenue¥6.5B
Founded2016
ModelBest
ModelBest
PRIVATE
Valuation¥20B
Total RaisedUndisclosed
Last Round2026
Moore Threads
Moore Threads
— (SSE)
Market Cap—
FY2025 Revenue¥1.505B
Founded2020
WeRide
WeRide
WRD / 0800.HK
Market Cap—
FY2025 Revenue~$93.6M
Founded2017
Pony.ai
Pony.ai
PONY / 2026.HK
Market Cap—
FY2025 Revenue$90.0M
Founded2016
Shengshu Technology
Shengshu Technology
PRIVATE
ValuationUndisclosed
Total Raised~$440M
Last Round2026
DiDi Autonomous Driving
PRIVATE
ValuationUndisclosed
Total Raised$1.39B+
Last Round2025
Unisound
Unisound
9678.HK
Market Cap—
FY2025 Revenue¥1.21B
Founded2012
Momenta
Momenta
06880.HK
Market Cap—
FY2025 Revenue¥2.4B
Founded2016
Qihoo 360
Qihoo 360
601360.SS
Market Cap~$10.1B
Market Cap~$10.1B
Founded2005
CXMT
CXMT
688825.SS
Market Cap—
IPO Proceeds~$8.6B
Founded2016
Manus (Butterfly Effect)
PRIVATE
Valuation~$500M
Total Raised$75M
Last Round2025
LimX Dynamics
LimX Dynamics
PRIVATE
Valuation¥15B
Total Raised~$400M+
Last Round2026
XPeng
XPeng
XPEV / 9868.HK
Market Cap—
ExchangeNYSE: XPEV · HKEX: 9868
Founded2014
AGIBot
AGIBot
PRIVATE
Valuation~$1.5B+
Total Raised$84M+
Last Round2025
Huawei
Huawei
PRIVATE
FY2025 Revenue¥880.9B
R&D Investment¥192.3B
Founded1987
Pragmatik Labs
Pragmatik Labs
PRIVATE
Valuation$2B
Total Raised$220M
Last Round2026
RedNote (Xiaohongshu)
PRIVATE
Valuation~$70B
Total Raised~$917M+
Last Round2026
JD.com
JD.com
JD / 9618.HK
Market Cap—
FY2025 Revenue¥1,309.1B
Founded2004
Data methodology: Funding data on this page is compiled from publicly available sources — company press releases, regulatory filings, and media reports — and fact-checked by Tony Peng with the assistance of AI. Where a round appears in both a company disclosure and press report, company disclosure takes precedence. All figures may be approximate.
Shipped Products
Applications
AI products from China's leading companies, by category
Est. 2026

The essential tracker for China's AI ecosystem

One place to follow every major model release, funding round, product launch, and breakthrough from China's AI ecosystem.
Tony Peng
Tony Peng
AI observer · Journalist · Communications professional

China AI Index is a research project built and maintained by Tony Peng — a long-time observer of the AI industry with a background in journalism and communications — with the assistance of AI (Claude Code, Qoder, and Z Code). Tony is also the writer behind Recode China AI, a newsletter tracking the latest advances and news stories in intelligent technologies.

It exists to give English-speaking researchers, investors, journalists, and developers a structured reference for China's AI ecosystem — most authoritative information is published in Chinese, and this site translates and synthesizes it.

Models
Every major LLM, reasoning model, vision model, and generative AI model from Chinese labs — with benchmark scores, context windows, and live API pricing so you can compare apples to apples.
Financing
Full funding histories for private companies (ByteDance, DeepSeek, MiniMax, Moonshot…) and market data for public ones (Alibaba, Baidu, Tencent, Kuaishou). Valuations, investors, round sizes.
Newsfeed
News covering model launches, research breakthroughs, product announcements, and strategic moves — presented in a clean timeline with company tags and category filters.
People
Key founders, CEOs, CTOs, and researchers behind China's AI labs — with titles, Chinese names, and links to their social profiles so you know the faces shaping the industry.
Members
Regulation
A timeline of China's AI rules — generative AI measures, algorithm filing requirements, model approval lists, data law touchpoints, and provincial subsidy programs. Click any entry for the original text.
Members
Chips
Domestic AI accelerators, training clusters, and memory chips — specs, interconnect bandwidth, process nodes, and deployment status for China's emerging chip ecosystem.
Data Disclaimer

All pricing, benchmark scores, funding amounts, and valuations are sourced from public company announcements, tech media reporting, and developer documentation. They are provided for informational purposes only and may be approximate or subject to change.

Stock prices shown are approximate historical ranges — not real-time quotes. Always verify with a live financial data source before making investment decisions. Benchmark scores reflect results at the time of model release and may not account for subsequent updates.

This database is independently maintained and has no affiliation with any of the companies listed. Information is updated manually on a best-effort basis.

Newsletter
Recode China AI
Weekly intelligence on China's AI ecosystem, from Tony Peng — straight to your inbox.
Get in touch
Leave a message
Have a correction, suggestion, or just want to say hello? Send a note — Tony reads every message.
✓ Message sent! Tony will get back to you soon.
2026 Sep
TC260Agentsdraftcybersecurity
Effective: Open for comment Issuer: TC260 Type: Draft for comment

Extends the August deployment-side guide upstream to agent system development. Together the two documents suggest TC260 is building a build-and-run pair for agents ahead of any binding rule.

View Official Text ↗
2026 Sep
TC260sectoraleducationhealthcaremedia
Effective: 2026-09-15 Issuer: TC260 secretariat, 网安秘字〔2026〕118号 Type: Practice Guide

Four documents released together, the start of a general-plus-sector series. The General Principles apply across all industries; the other three give sector-specific security practice guidance for education, health, and broadcasting/online audiovisual. Drafting units include CESI, the NRTA research academy, NHC and MOE information centers.

View Official Text ↗
🔒 14 more regulations — Paid Subscribers Only
You're viewing the first 2 entries free. The full regulation timeline — 16 laws, measures, and strategy documents back to 2017 — is included with a paid Recode China AI subscription.
Not a paid subscriber? Upgrade on Recode China AI →

China's Chip Ecosystem

Domestic AI accelerators, large-scale training clusters, and memory chips — tracking the hardware layer behind China's AI buildout.

AI Accelerators
Clusters & Supernodes
Memory & HBM
Role
Precision
Company ↕ Chip ↕ Role Peak Compute ↕ Memory Tech Capacity ↕ Bandwidth ↕ Interconnect
Bandwidth ↕
TDP ↕ Process Status Highlights
Huawei ↗
Ascend 910B
Training
256 TFLOPS
BF16
HBM2e 64 GB 2.0 TB/s
392 GB/s
HCCS 3.0
400 W SMIC N+2 Production Most-deployed domestic training chip. Used at Alibaba, ByteDance, Baidu, and Tencent.
Huawei ↗
Ascend 910C
Training
800 TFLOPS
FP16
HBM2e 96 GB 4.0 TB/s
800 GB/s
HCCS
900 W SMIC N+2 Production Dual-die upgrade to 910B. Powers the Atlas 900 A3 SuperPoD (300 PFLOPS).
🔒 18 more accelerators — paid subscribers only
Specs marked ~ are estimates from third-party analysis. Click any column header to sort. Interconnect Bandwidth = chip-to-chip fabric bandwidth per chip (bidirectional).
Cluster / Supernode Operator Chip Chip Count Total Compute Interconnect Fabric Notes
Atlas 900 A3 SuperPoD (CloudMatrix 384)
Huawei Cloud Ascend 910C 384
300 PFLOPS
FP16
All-optical (OXC) Huawei's current-generation supernode. Uses optical circuit switching (OXC) for low-latency inter-chip communication. Announced April 2025 as a full-stack domestic alternative to Nvidia GB200 NVL72.
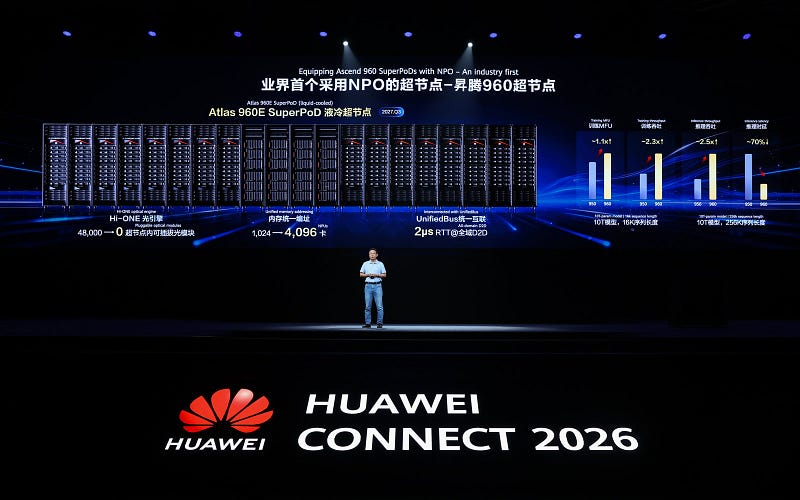
Atlas 950 SuperPoD
Huawei Cloud Ascend 950 8,192
8 EFLOPS
FP8
16.3 PB/s aggregate Next-generation supernode targeting 2026 delivery. 1,152 TB total memory. Full liquid cooling. Footprint larger than two basketball courts. Would represent a major leap in domestic training capacity if delivered at spec.
🔒 3 more clusters — paid subscribers only
Cluster sizes and compute figures are from official announcements or credible press reports.
Company Product Type Capacity Bandwidth Process Status Notes
CXMT ↗
DDR5
DDR 16–32 Gb dies ~6400 MT/s ~16nm (G4) Production CXMT's latest-generation DDR5, unveiled Nov 2025 — its push into the high-end DRAM market against Samsung, SK Hynix, and Micron.
CXMT ↗
LPDDR5X
LPDDR Mobile ~8533 MT/s ~16nm Production Low-power mobile DRAM for smartphones and edge/AI devices.
🔒 2 more memory chips — paid subscribers only
DRAM, HBM, and NAND from Chinese memory makers. Specs marked ~ are estimates from third-party analysis or press reports.
🔒 Free Preview — Paid Subscribers Only
You're seeing the first 2 rows of each table. Full specs for 20 accelerators, 5 clusters, and 4 memory chips are included with a paid Recode China AI subscription.
Not a paid subscriber? Upgrade on Recode China AI →
Compare